If you've ever wondered whether it's the AI model or the coding tool wrapped around it that actually decides your results, one writer at XDA Developers just ran the experiment that answers the question, at least for one case.
The setup: Claude Code, OpenAI's Codex, and Cursor, all pointed at the same Claude Sonnet 5.5 model running at high reasoning. Same buggy WebSocket proxy script, built to feed Kindle data from Home Assistant. Same 30 minutes. Same $10 budget per tool.
Getting the models to match wasn't simple. Cursor needs a subscription to call third-party models at all, and Grok is the one exception it won't touch outside that. Codex has an official route through OpenRouter. Claude Code, built to talk only to Claude, meant using it as intended was the only way to keep the test honest, since bolting on outside models would add an unsupported translation layer.
The code came out nearly the same
All three tools produced code that passed all 16 tests in the final grading routine, kept deliberately hidden from the agents so they couldn't write around it. Where the task was narrow and well-defined, like fixing a specific bug, Codex and Claude Code even used the same function names, a pattern the writer calls "an underlying fingerprint of Sonnet 5.5" rather than something the tools themselves introduced.
All three also added fixes nobody asked for: a banner for when the Kindle loses its connection, a patch for a malformed JSON crash, and a fix for a return-versus-continue bug. None of that was in the task brief.
The gap showed up once the brief got open-ended. Asked to restructure a messy proxy module, Codex patched the existing code and left most of it intact. Cursor rewrote more aggressively, keeping 43% of the original file. Claude Code went furthest, stripping the file down to 34% of its original form.
Testing habits diverged just as much. Codex ran ten tests. Cursor ran 33. Claude Code ran 42, because it repeated the same test suite three times to confirm its own results, and at one point reintroduced the original bug on purpose just to prove its tests would catch it.
One detail stood out beyond the test metrics. The source repo's interface text was in German. Codex and Cursor kept rewriting UI elements in German. Claude Code defaulted to English instead, a quirk the writer declined to explain with confidence either way.
The takeaway isn't that one tool beat the other two on this run, because the grading tests came out even. It's that the model doing the thinking and the harness running it aren't interchangeable the way a lot of people assume. Pick Claude Code, Codex or Cursor for the same Claude model and you can expect the core logic to land in roughly the same place, but how much testing you get, how conservative the refactor is, and small defaults like language choice still depend on which wrapper you're running.
This was a single test on a single codebase with a single model, run by one writer rather than a formal benchmark. Anyone choosing between these tools for a bigger project should weigh that before drawing firm conclusions from it.
ADFiled by The AI Desk
Models, assistants and the companies and chips behind them, reported from what was released and what was claimed, with the difference kept clear.
More from this desk →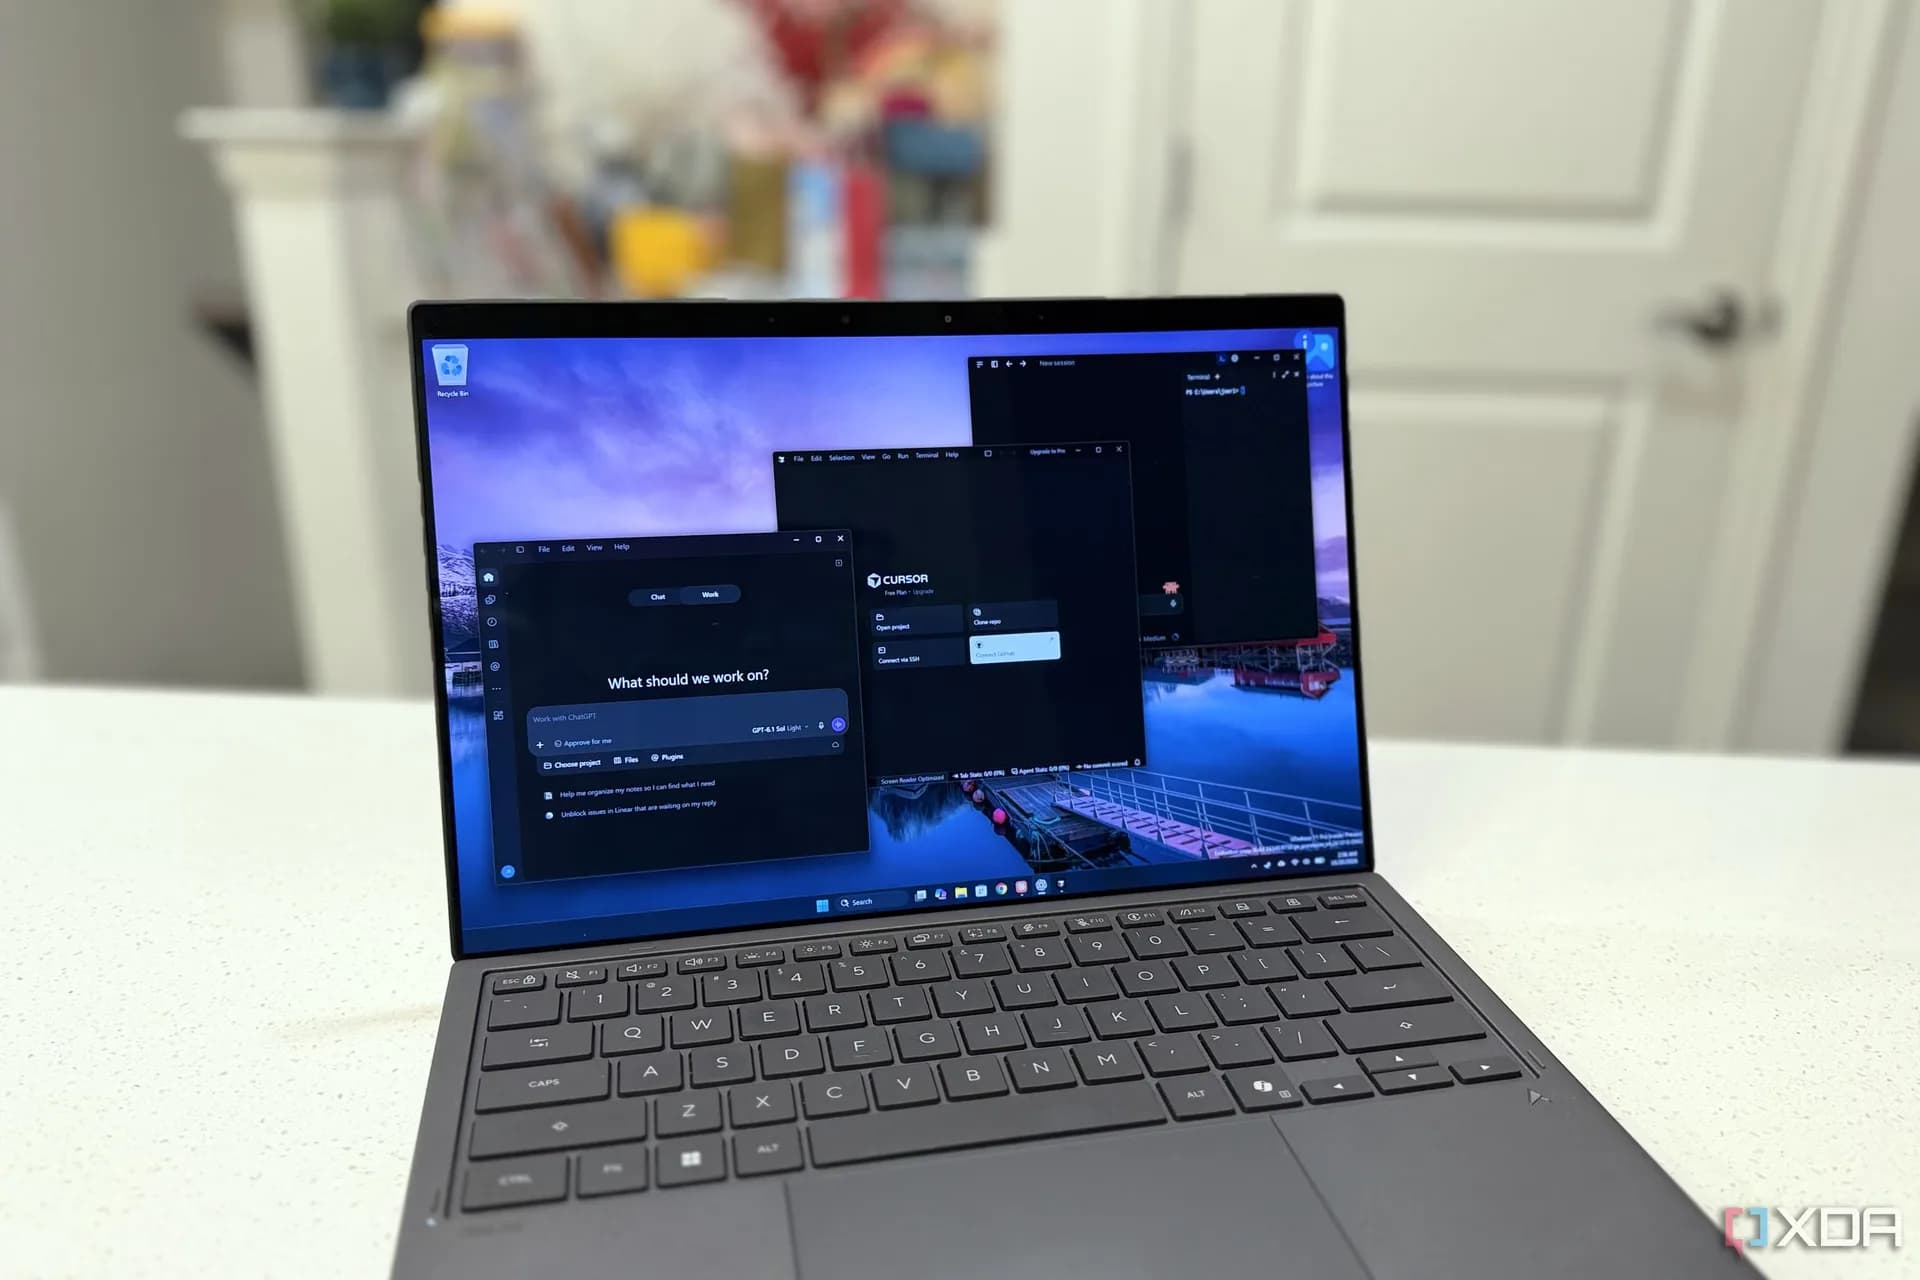
Be the first to comment
Join the argument. No password, just your email or a passkey.