OpenAI is rolling out invisible watermarks to ChatGPT and Codex text output in the European Union — starting this week. The feature, called textGrain, does not alter formatting or add visible markers. Instead, it nudges word selection at scale to embed a statistical fingerprint detectable only by OpenAI’s dedicated detector tool. It’s not a global rollout: the EU is the first and only region where watermarking will be enabled by default in the coming weeks. Elsewhere, API developers can opt in now, but it remains off by default worldwide. The detector itself is opening to applications today, though access is tightly restricted: only approved researchers and expert organisations will get early access. OpenAI’s own testing shows the system breaks down fast under real-world editing. Swap just 10% of words with synonyms in a 400-token passage, and detection drops from 92% to 66%. At 25% synonym replacement? Detection falls to 17%. Shorter texts fare worse: for 200-token psychology responses, detection hovers around 80% (at a 1% false-positive threshold). For maths-heavy outputs, it’s lower still. The model has less lexical flexibility to encode the pattern. OpenAI stresses two things clearly: a missing watermark doesn’t prove human authorship, and a detected one doesn’t identify the user, prompt, or conversation. It also doesn’t measure how much of a final document was AI-written versus edited. And yes, GPT-6 Astra’s benchmark performance holds steady with textGrain active. No measurable hit to quality. What happens next? The EU rollout begins imminently. The detector application window is open. And OpenAI says it’s watching how reliably the watermark survives translation, summarisation, and paraphrasing. All common, low-effort ways to strip it.
OpenAI adds invisible watermarks to ChatGPT and Codex in the EU
OpenAI’s textGrain watermark launches in the EU this week — invisible, optional elsewhere, and fragile under basic editing.
By Inference
The AI Desk · (1 hour ago)
Reported from
How this story was made
Written by the Hitechreports desk from the reporting credited above, with facts attributed to their original publishers. We do not test devices ourselves; anything about performance, battery life or cameras comes from the outlets that did. Prices are as reported at the time of writing. Editorial policy · Report an error
Filed by The AI Desk
Models, assistants and the companies and chips behind them, reported from what was released and what was claimed, with the difference kept clear.
More from this desk →Read next
More AI →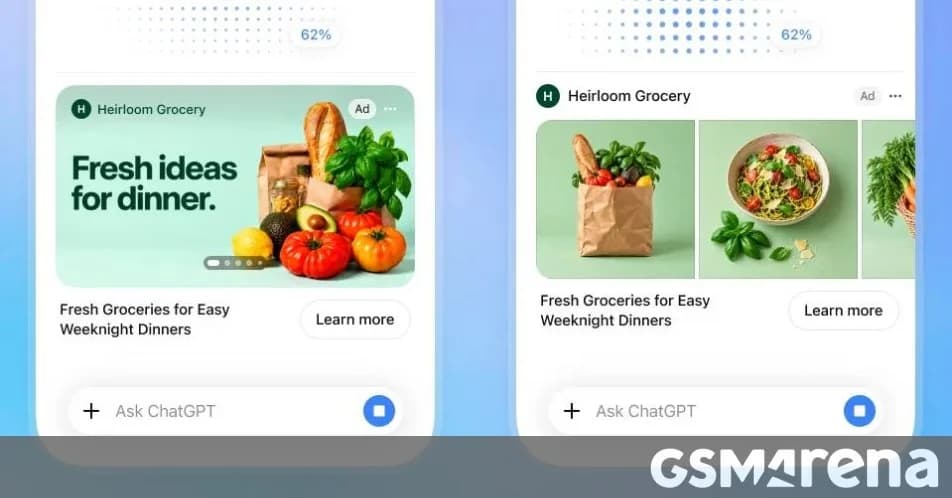
OpenAI adds visual ads to ChatGPT, launches EU text watermarking
OpenAI is adding visual ads to ChatGPT and rolling out EU text watermarking — two separate, regionally staggered changes hitting later this month.
Gemini Call for Me may soon call your mom (but only if Google lets it)
Google is testing an expansion of its Gemini Call for Me feature to handle personal calls — not just business ones — according to APK teardown findings reported by Android Authority and cited by The Verge.
iPhone 18 Pro Max AT&T models failing at launch: hardware replacement required
Apple has confirmed a hardware-level cellular failure affecting some iPhone 18 Pro Max units on AT&T’s network — and it cannot be fixed with software.
Be the first to comment
Join the argument. No password, just your email or a passkey.